Data Scientist: Finds patterns and builds predictive models from data — a 2008 job title built on three centuries of counting, testing and visualizing evidence.
A data scientist extracts patterns, predictions and recommendations from data using statistics, programming and domain knowledge, then turns the result into something a business, government agency or research team can act on. The work spans writing SQL to pull data out of a warehouse, cleaning and reshaping it, fitting a statistical or machine-learning model, and explaining what the result does and does not support.
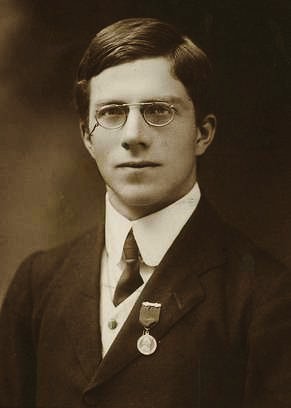
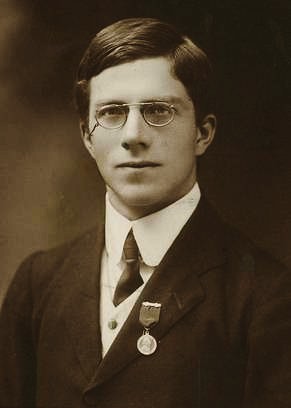
The job title is far younger than the craft behind it. 'Data scientist' dates to around 2008, when DJ Patil and Jeff Hammerbacher independently settled on it while building data teams at LinkedIn and Facebook, and statistician William S. Cleveland proposed 'data science' as an academic field only in 2001. The underlying discipline is centuries older, tracing through John Tukey's 1960s-70s push for exploratory data analysis back to Ronald Fisher's 1920s statistics and John Graunt's 1662 study of London's mortality records.
A 2012 Harvard Business Review article calling it 'the sexiest job of the 21st century' triggered a decade-long corporate hiring boom and hundreds of new university programs. That boom has since matured: the generalist title has split into analytics engineering, machine learning engineering and product analytics, and AI tools now handle a growing share of the routine querying, cleaning and charting the original job assumed a person would do by hand.
Inside the profession
Data science is the craft of turning imperfect records into decisions, where the hard part is rarely fitting a model and usually deciding what the data can honestly support.
Most of the day is evidence work
Working data scientists query warehouses, reconcile definitions, inspect distributions, clean broken fields and explain uncertainty. Modeling is important, but a result only earns trust when its data lineage, assumptions and alternatives can be examined. The strongest practitioners can tell a stakeholder that a confident-looking chart answers the wrong question, or that an observed association is not evidence of a cause.
The title hides several careers
A product data scientist may design experiments and measure feature outcomes. An applied scientist may develop predictive models. A decision scientist may focus on operations, finance or policy. In mature organizations, analytics engineering, data engineering and ML engineering absorb parts of the older generalist job. Domain knowledge changes the work as much as technical stack: an experiment on a shopping app is not a study of patient outcomes or fraud.
The gate is demonstrated reasoning
Statistics, computer science, mathematics, economics and physical sciences all provide routes. A degree helps, but an interview or portfolio usually tests SQL, statistical reasoning, data quality and communication more directly. A credible project does not need a flashy model; it needs a clear question, documented data, an appropriate baseline and conclusions matched to the evidence.
AI compresses routine analysis
Assistants can draft SQL, charts, summaries and baseline models. That genuinely changes entry-level work. It does not settle measurement definitions, expose a hidden confounder, choose an ethical use for a prediction or accept accountability for a decision. The profession is moving toward problem framing, experimentation, causal reasoning and review of machine-generated analyses.
How the work branches
Five common shapes of the same title — specialty, setting or career path.
Digital products
Product data scientist
Uses metrics and experiments to guide product choices, while defending against misleading short-term optimization.
Predictive systems
Applied / machine-learning scientist
Builds and evaluates models for ranking, forecasting, detection or personalization, often alongside ML engineers.
Operations and strategy
Decision scientist
Combines data with business or public-policy context to support planning, allocation and risk decisions.
Growth and causal inference
Experimentation specialist
Designs controlled tests and quasi-experiments that distinguish an intervention from correlation.
Science and public research
Research data scientist
Works with complex observational or experimental data where reproducibility and methodological rigor outrank rapid product shipping.
How it reads by country
Same craft, different gatekeeping, status and daily texture — rewritten for readers in each language.
United States — specialized titles and interviews
Technology, finance and health sectors use the title differently, and recruiting often tests SQL, experiments and communication explicitly. High compensation is concentrated in a few cities and employers.
South Korea — platforms, commerce and enterprise data
Large consumer platforms, telecoms and conglomerates support analytics work, with Korean-language context often vital for product and customer data. Job titles can blur analyst and scientist roles.
Japan — enterprise data and careful adoption
Manufacturing, finance and consumer firms are expanding analytics while maintaining established data-governance practices. International teams may value English and cloud experience alongside local domain knowledge.
Germany — privacy and industrial context
Data protection and worker representation shape what data can be collected and used. Automotive, manufacturing and research employers create demand for people who can bridge statistics and real operations.
United Kingdom — London finance and research
Finance, consulting and product companies cluster heavily around London, while public research and universities offer different career incentives. Contract roles remain visible in the market.
Singapore — regional finance and platforms
Banks, government technology and regional headquarters create data roles spanning multiple markets. Regulatory expectations and cross-border data rules are frequent constraints.
From the archive
Commons CC/PD images self-hosted for this profession.
Why attitude matters here
A model can be statistically correct and still mislead a decision-maker; whether a data scientist says so before the deadline, not just when asked, is where attitude outweighs technique.
Reporting the finding that hurts the roadmap
An analysis that says a feature everyone wants to ship doesn't move the metric they hoped, or that a beloved growth channel is really just picking up existing demand, is unwelcome and easy to soften. Data scientists who report the inconvenient result anyway are the reason a company's decisions track reality; the ones who shade a finding toward what leadership wants to hear turn analytics into decoration.
Confessing the limits of a small sample
A five-day experiment or a thin cohort can produce a number that looks precise and is actually noise, and almost nobody downstream will check the sample size before acting on it. The attitude that separates a trustworthy analyst is refusing to let a number sound more certain than the data underneath it actually is, even when a confident number is the one a stakeholder wants.
Owning a model's real-world consequence
A model that denies a loan, ranks a résumé, or flags a patient does something to a person who never sees the notebook it came from. Because the model's author is usually the only one positioned to notice a subtle bias or a leaking feature before deployment, taking that responsibility seriously — rather than treating the model as someone else's problem once it ships — is where the harm actually gets caught.
Stances that hold up under pressure
Five concrete postures the work rewards, not slogans.
Plots the raw data before touching a model
Looks at distributions, outliers and missing values with their own eyes before fitting anything, on the assumption that a model will quietly absorb whatever is broken in the data rather than flag it for anyone.
States uncertainty in the same sentence as the finding
Reports a confidence interval or a caveat alongside a headline number instead of only after it is challenged, so a stakeholder cannot mistake a rough estimate for a precise one simply because the uncertainty was left unsaid.
Hunts for the confound before celebrating a result
Treats a surprising, convenient-looking correlation as a problem to investigate rather than a result to present, because the more a finding flatters the team's preferred plan, the more it deserves scrutiny.
Kills their own pet analysis when the data doesn't hold
Abandons a favorite hypothesis once the evidence stops supporting it, rather than running one more cut of the data hoping for a result that finally survives the test, and says so plainly in the write-up.
Says the data can't answer the question asked
Tells a stakeholder plainly that the available data cannot support a confident answer, instead of producing a number anyway simply because a number was requested and a blank slide felt unacceptable to present.
Moments that reveal it
Situations that separate résumé language from how someone actually practices.
The experiment that shows the favored feature doesn't work
Leadership already announced the launch date before the A/B test finished. The results show no real lift. Whether the analyst reports that plainly, or finds a secondary metric that looks better, reveals what the job actually is.
A model performs well until it meets a subgroup it wasn't tested on
Aggregate accuracy looks strong, but a breakdown by demographic or region reveals the model fails one group disproportionately. Noticing this before deployment, unprompted, separates analysts who check from ones who report the average and move on.
A client wants a number more precise than the data supports
A three-week-old dataset gets asked to justify a firm annual growth projection. Delivering a confident-sounding figure is easy and welcome; explaining why the data can only support a rough range is harder and far less popular.
The dashboard everyone trusts is quietly wrong
A widely used metric has a subtle bug that happens to make performance look good, and nobody upstream has complained about it. Flagging it means admitting a mistake and disappointing people who liked the old number.
Where "calling" turns harmful
"Data-driven culture" as cover for predetermined answers
Companies that market themselves as rigorously data-driven sometimes use that language to pressure analysts into finding support for a decision already made, treating one who reports an inconvenient result as not a "team player." The field's early hype as a glamour job also normalized unpaid overtime dressed as curiosity — staying until midnight for one more cut of a dataset gets praised as passion, not questioned as a workload problem.
The profile
Resists AI38
Pay74
Barrier to entry55
Autonomy60
Demand78
Impact66
How exposed is it to AI?
High
A meaningful share of routine data-science work — SQL querying, exploratory charting, fitting a standard model with AutoML, writing boilerplate pipeline code — is already automatable or AI-assisted today, and that share is growing quickly. What resists automation is framing an ambiguous business problem as a testable question, judging whether a result is real or a statistical artifact, and being accountable when a model's real-world decision turns out to be wrong.
What does a data scientist actually do day to day?
Contrary to the 'building AI models' image, most days split between writing SQL queries and Python code to pull and clean data, running statistical tests or training models, and translating results into a chart or memo a non-technical stakeholder can act on. Practitioner surveys consistently put data cleaning and preparation at roughly half or more of total working time.
Do you need a PhD to become a data scientist?
No. Unlike medicine or law, there is no license or single required degree; a bachelor's or master's in statistics, computer science, mathematics or a related quantitative field is the most common path, and a strong portfolio of real projects often matters more to employers than the exact credential. PhDs are more common in research-heavy or applied machine-learning roles.
Is data science just statistics with a new name?
Not quite. It draws heavily on statistics — Fisher's experimental design, Tukey's exploratory analysis — but adds programming, database engineering and machine learning that classical statistics departments rarely taught. William S. Cleveland proposed the term in 2001 specifically to describe this enlarged, computing-heavy version of the field, built on statistics rather than replacing it.
Is data science at risk from AI?
The routine end is already exposed: AutoML tools can fit and tune standard models, and AI assistants can write SQL queries, first-draft exploratory charts and boilerplate pipeline code faster than a person. What has not been automated is framing the right question, judging whether a pattern is meaningful or spurious, and taking responsibility for a decision built on the result.
How much do data scientists earn?
It varies widely by country and seniority. The US Bureau of Labor Statistics put the median annual wage for the Data Scientists occupation at roughly $108,000 in 2023, while junior analysts often start closer to $70,000-$95,000 and senior or principal data scientists at major technology companies can earn $200,000-$400,000 or more in total compensation with equity.
What's the difference between a data scientist, a data analyst and a machine learning engineer?
A data analyst typically answers defined business questions with existing data and dashboards; a data scientist builds new statistical models and predictive analyses, often from messier data; a machine learning engineer takes a model out of a notebook and makes it run reliably, at scale, in production. The lines blur constantly, and many people move between all three across a career.
What tools and programming languages does data science use?
Python dominates, usually paired with libraries like pandas and scikit-learn, alongside SQL for querying databases. R remains common in academic and biostatistics-heavy settings. Jupyter notebooks are the standard environment for exploratory work, and cloud data-warehouse platforms such as Snowflake, BigQuery or Databricks now hold the data most data scientists actually query.
Why was 'data scientist' called the 'sexiest job of the 21st century'?
Thomas Davenport and DJ Patil used that phrase as the title of their October 2012 Harvard Business Review article, arguing that the rare combination of statistical skill, coding ability and business judgment the role required made it both scarce and highly sought after. The phrase stuck, helping trigger a decade-long corporate hiring boom and dozens of new university degree programs.
Embed this ranking
Paste this code into your blog or site — the ranking stays up to date.